Sample project
Pumpkin soup prep: 27 classes, 28 tracks and per-frame depth
TrackingDepthActions & Captions
- Data
- Video · 1920×1080
- Volume
- 150 frames · 3,424 labeled instances
- Status
- Sample project
The problem
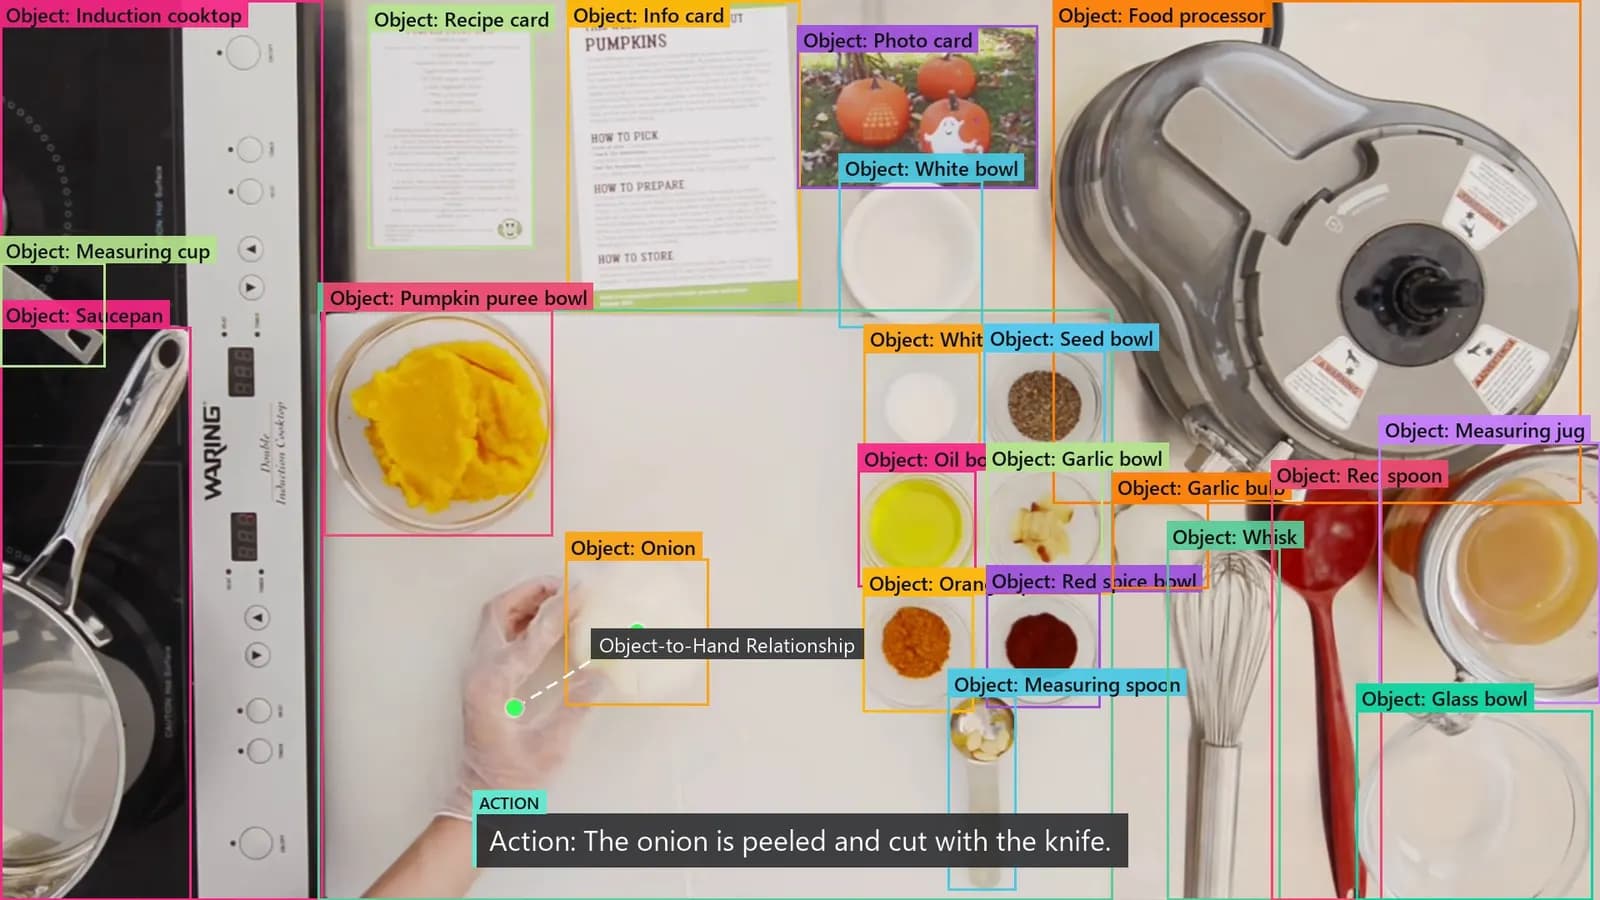
Crowded scenes with many similar containers (spice bowls, jars, pans) are where trackers swap IDs, and 2D boxes alone don't tell a robot how far away anything is.
What we did
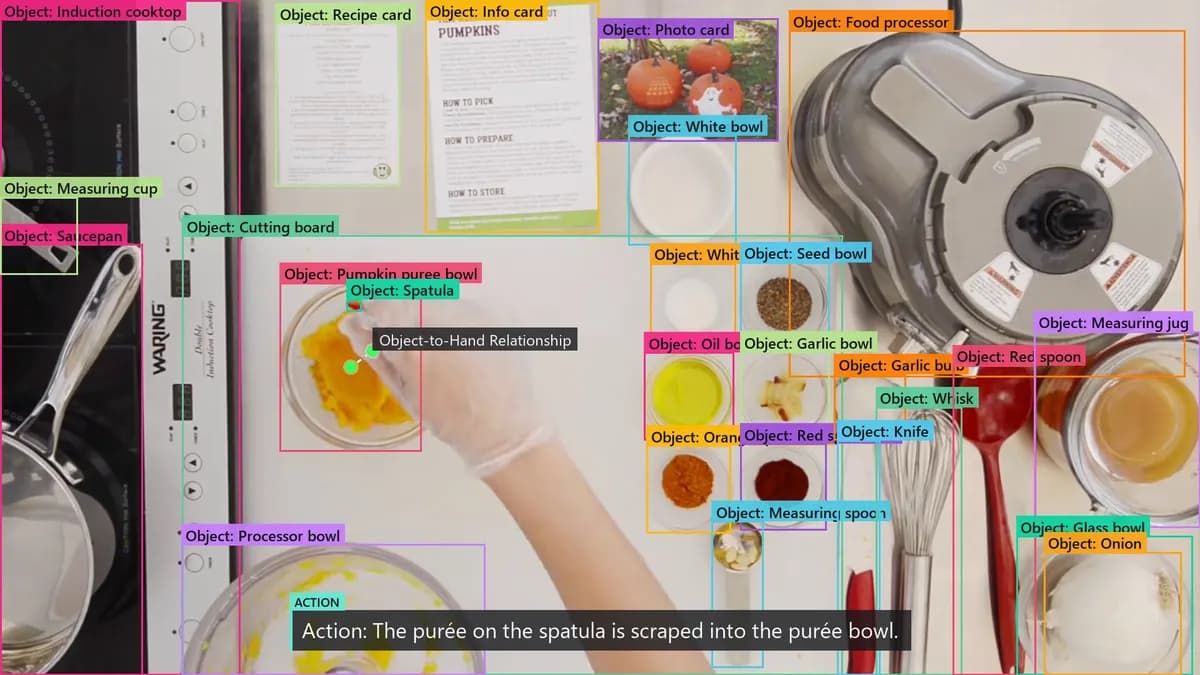
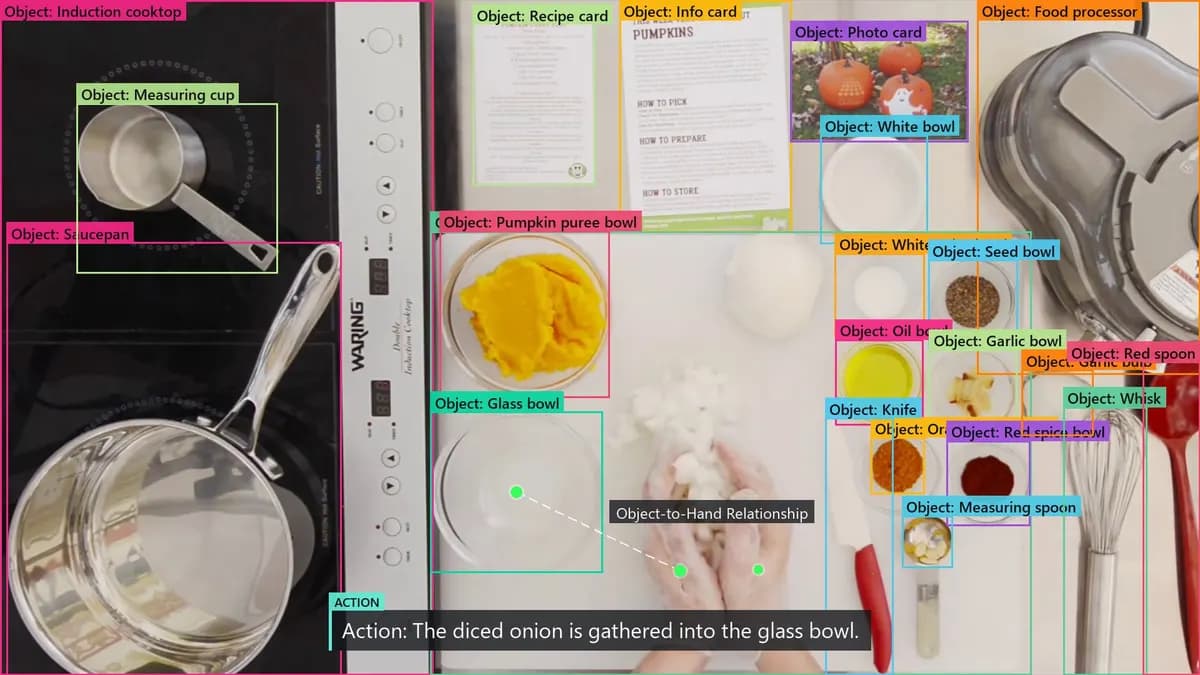
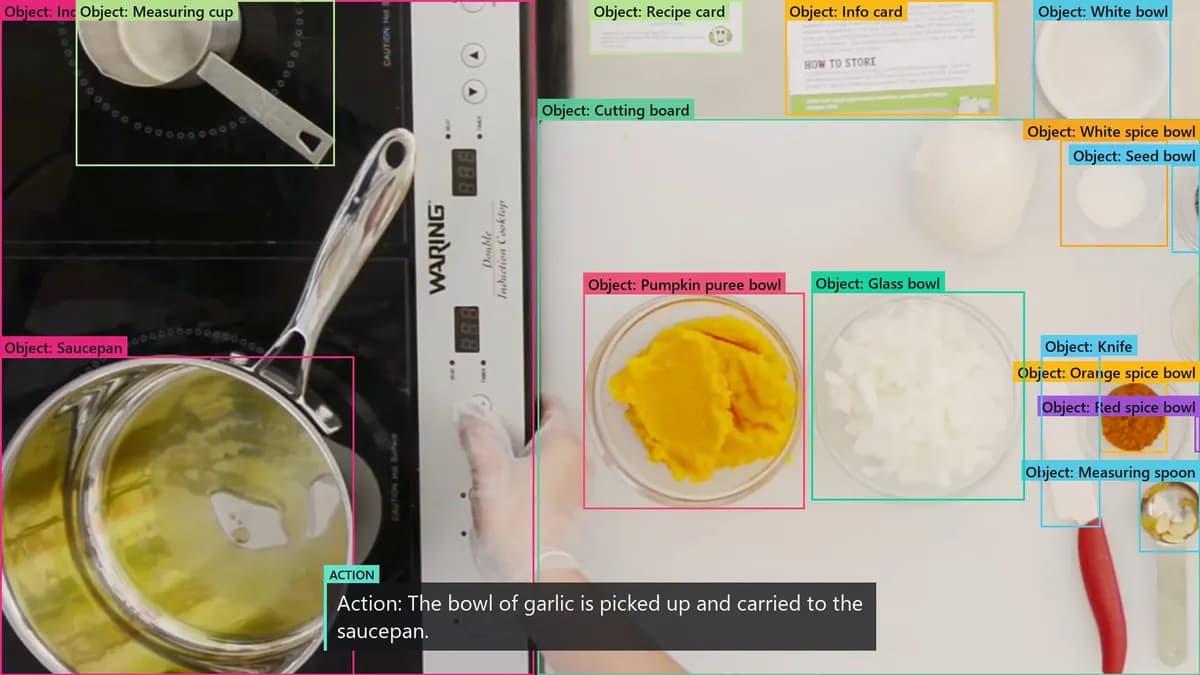
- 27 object classes, 28 tracks, 3,424 labeled instances
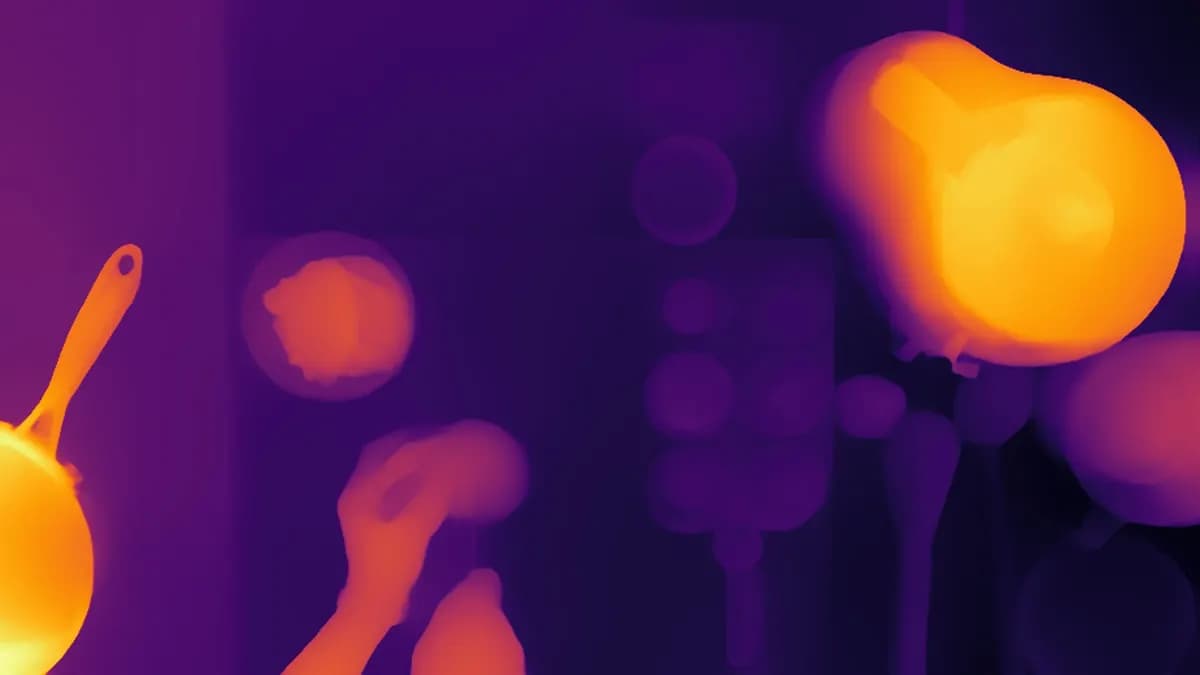
- Monocular depth estimated per frame and exported alongside the labels
- 3D trajectories derived for tracked objects
- 12 action captions and 14 hand-object contacts, reviewed
Result
150 labeled frames with depth maps, 3D trajectories and captions, exported as a training-ready dataset.
Labeled video · 30 seconds
- Caption track
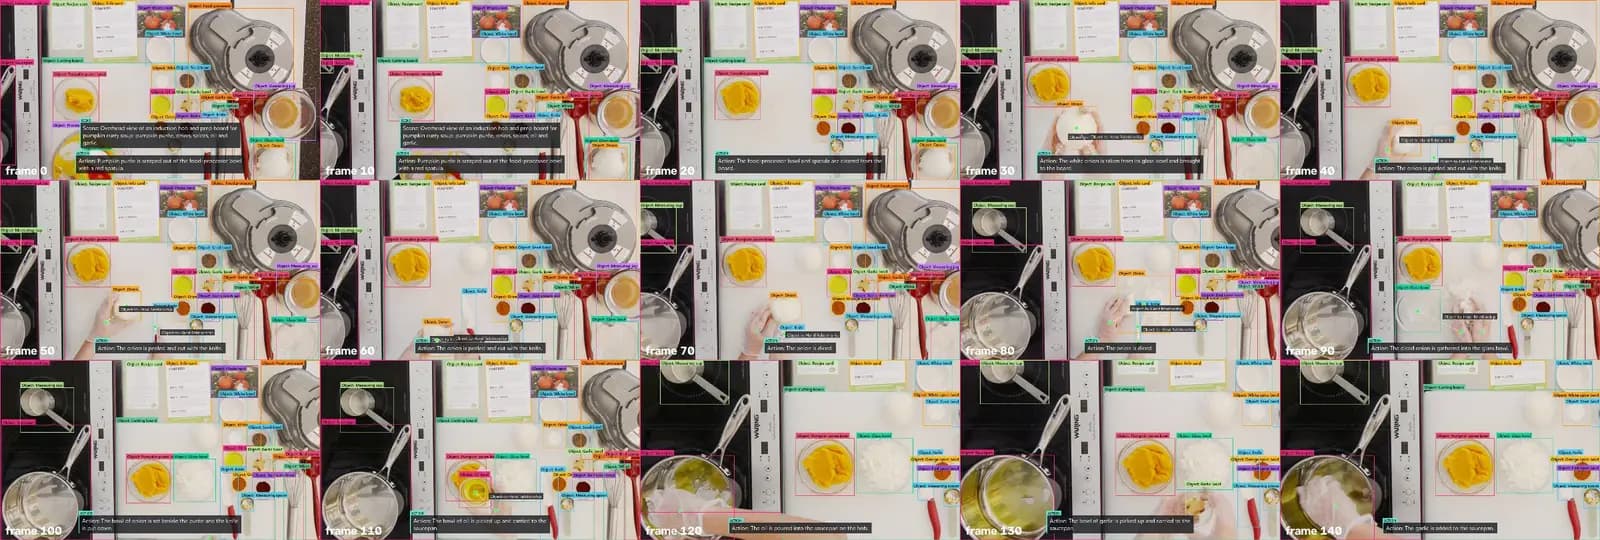
- 00:00Pumpkin purée is scraped out of the food-processor bowl with a red spatula.
- 00:02The purée on the spatula is scraped into the purée bowl.
- 00:04The food-processor bowl and spatula are cleared from the board.
- 00:05The white onion is taken from its glass bowl and brought to the board.
- 00:06The onion is peeled and cut with the knife.
- 00:13The onion is diced.
- 00:18The diced onion is gathered into the glass bowl.
- 00:20The bowl of onion is set beside the purée and the knife is put down.
- 00:21The bowl of oil is picked up and carried to the saucepan.
- 00:23The oil is poured into the saucepan on the hob.
- 00:25The bowl of garlic is picked up and carried to the saucepan.
- 00:28The garlic is added to the saucepan.
Frames, depth and review sheet
Sample output
An excerpt from the delivered files. "source": "ai" marks boxes propagated by the segmentation model; every one was reviewed by a person before export.
pumpkin.jsonexcerpt
{
  "image_id": 55,
  "category": "induction cooktop",
  "bbox": [0, 0, 387, 1080],
  "attributes": {
    "track_id": "obj_d5b24e576f65",
    "keyframe": true,
    "source": "ai"
  }
}
Source footage: “Pumpkin Curry Soup”, US Department of Agriculture (Agricultural Marketing Service), via Wikimedia Commons (Public domain). Labels, captions, tracks and depth by Annoroid.